Zero copy usually means one system can access or query data in another platform without creating a separate persistent replica for that exchange. In customer-data architecture, the term is useful only when you know which data stays in place, which data may still move, and how access, computation, and outputs are governed.
The label is not a complete architecture. Different vendors apply it to warehouse queries, secure data sharing, storage ownership, or a composable application pattern. A technical evaluation should examine the actual data path rather than accept the phrase as proof of simplicity or control.
Key Takeaways
Zero copy reduces persistent data replication for a defined connection or workflow, but it does not mean that no data is ever cached, transformed, exported, or activated elsewhere.
The main benefits can include fresher access, fewer pipelines, clearer storage control, and less reconciliation between copies when the implementation supports them.
Buyers should map raw data, derived profiles, compute, model outputs, and activation data separately because each may follow a different path.
Amperity Bridge supports access to shared tables in Databricks, Google BigQuery, and Snowflake without replication, according to current Amperity documentation.
What does zero copy mean?
Zero copy is an architecture pattern that lets an application access data where it already resides or through a shared representation instead of maintaining another persistent copy for that purpose. The precise mechanism may be a secure share, shared catalog, open protocol, warehouse query, or table format.
The scope matters. A platform may provide zero-copy access to source tables while still writing derived profiles, feature data, logs, exports, or activation files somewhere else. That can be appropriate, but the buyer should understand and govern each additional artifact.
What problems can zero copy solve?
Reduce data movement and reconciliation
Every persistent replica creates another dataset to refresh, secure, catalog, and reconcile. Sharing or querying a governed dataset directly can reduce the pipelines and version drift created when the same information is copied into several vendor environments.
Keep access closer to existing governance
When data remains in an environment the organization already governs, existing access controls, monitoring, and storage policies can continue to apply. Zero copy does not remove the need to govern the application, its queries, derived outputs, credentials, or downstream use.
Improve freshness for supported workflows
Direct access to shared data can remove a scheduled replication step. That can make newer data available sooner, but freshness still depends on source updates, table maintenance, identity processing, query behavior, caches, and the systems that consume the result.
Lower integration overhead
A supported sharing mechanism can replace custom pipelines for some exchanges. Teams still need to configure permissions, data contracts, quality checks, monitoring, and change management. Zero copy reduces certain moving parts; it does not eliminate architecture work.
What zero copy does not guarantee
Zero copy is not the same as zero storage, zero compute, zero latency, or zero governance. It also does not guarantee that customer records have been resolved into accurate profiles or that the data is appropriate for every downstream use.
A warehouse can hold all customer records without knowing which records describe the same person. Identity resolution, profile logic, consent, lineage, and activation controls remain separate requirements. The architecture should help those capabilities work together rather than treating storage location as the entire customer-data problem.
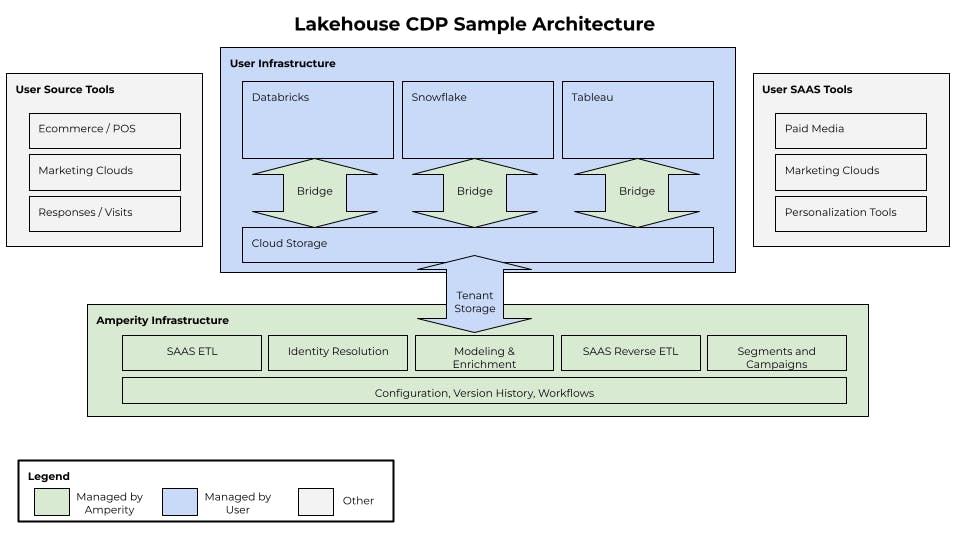 Lakehouse CDP architecture that unlocks all three benefits referred to by "zero copy."
How Amperity approaches zero-copy sharing
Amperity Bridge connects Amperity with data warehouses through industry-standard sharing mechanisms. Current documentation states that organizations can access shared tables in Databricks, Google BigQuery, or Snowflake without copying the data and can configure inbound and outbound shares where supported.
Bridge is one part of a broader customer-context architecture. Amperity can combine lakehouse access with identity resolution, unified profiles, real-time signals, governance, intelligence, and activation so teams and AI can use customer context, not only query source tables.
Questions to ask a zero-copy vendor
Which specific datasets are accessed without replication, and which datasets or outputs are still copied?
Where do query compute, identity processing, models, caches, logs, and derived profiles run?
How are access, revocation, lineage, retention, and deletion managed across the full workflow?
What happens when a source schema, permission, table, or sharing configuration changes?
How fresh is the data at the point of decision or activation, and what steps can introduce delay?
Which warehouse and lakehouse products, regions, table formats, and sharing directions are supported for your deployment?
Explore how Amperity works with your existing data architecture and makes trusted customer context available across teams and tools. Request a demo to review your zero-copy and lakehouse requirements.